A client sent me a screen recording last week of an application he is about to launch. It is a SaaS product for dental laboratories: case intake, job tracking, and the paperwork a lab otherwise keeps in a folder and a WhatsApp thread. He is in the final round of testing. The interface is clean, the workflows are finished, and it is nearly ready for customers.
He built it with a Hermes agent on a dedicated VPS, running DeepSeek. Not "with AI assistance" in the way that phrase usually means, where a model suggests a function and a human pastes it in. The agent worked on the server. It had the repository, the shell, the git history and the deployment target. Every change went through GitHub. When the application was ready, the agent published the website to the production server itself.
Then he did something I found more interesting than the launch.
The second opinion
He had been on ChatGPT Pro before he moved to one of our agents. He has been running ours for a month now and told me he is impressed. But he wanted a control group, so he handed the finished application to ChatGPT for a review. A second pair of eyes, from the most famous model on the market.
The review came back with a list of problems. Missing pieces, broken paths, things that would not work. It read like a serious audit.
None of the items held up.
He asked the Hermes agent to check the list against the actual codebase. The agent opened the files, read the functions, checked the schema, looked at the deployment, and went through the claims one by one. Each reported problem turned out to be either not there, already handled, or a misreading of a file ChatGPT had never seen. The agent did not argue. It showed the evidence: this file, this line, this commit, this endpoint answering on the server.
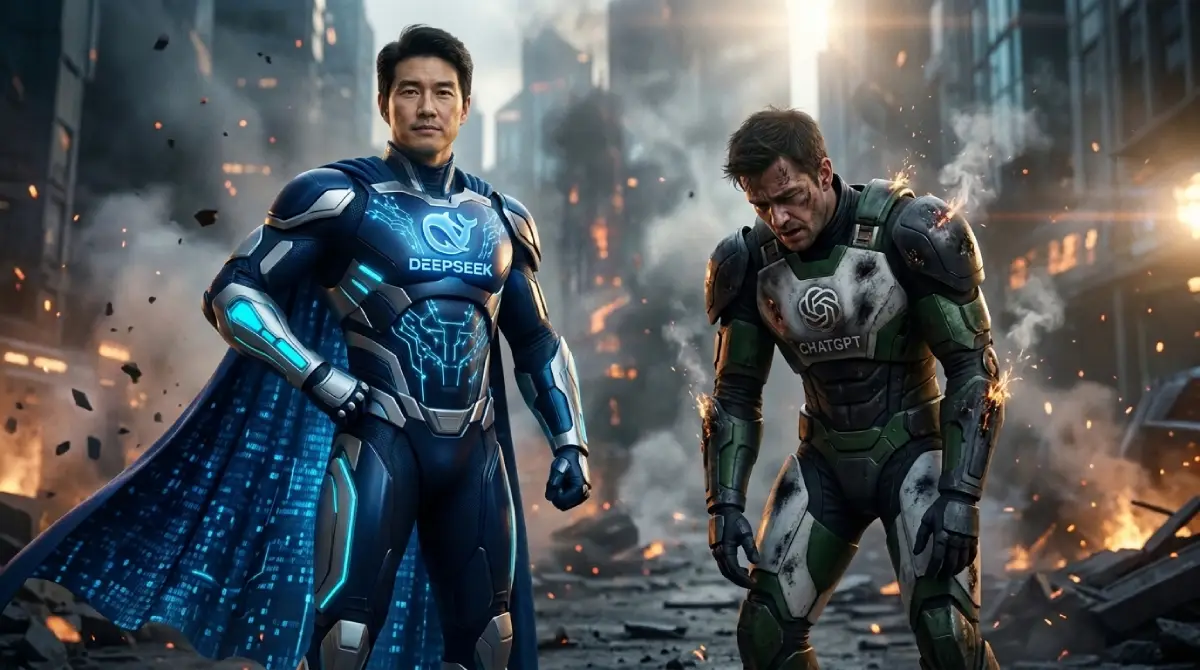
The less expensive model, on a properly built setup, debunked the famous one in minutes. That is the part worth writing down.
But the conclusion most people jump to is the wrong one. It was not a contest between two language models. The two reviewers were never in the same race.
Why that review was never a fair fight
ChatGPT was handed a codebase as text in a chat window. It had no filesystem. It could not open a file it had not been given, run a test, read the git log, query the database, or see what the server was actually serving. Everything it said about the application had to be inferred from a description of the application.
So it did what a language model does when it cannot check. It produced the most plausible answer. And a plausible answer about software sounds exactly like a real one. "There is no error handling here" is true of almost every young codebase and false of this one. "This will break on deployment" is a reasonable guess about any application. A guess is not a finding.
The Hermes agent had the opposite problem: it could check, so it had to. Nothing in its answer needed to be inferred, because the evidence was one command away.
That is the whole difference, and it has almost nothing to do with model quality. A model without a filesystem is a very well-read person on the phone. It can talk about your code. It cannot look at it.
What infrastructure actually means
When I say the infrastructure matters more than the model, I do not mean a bigger server. I mean the environment the model works inside.
A real machine with a shell, so it can run what it writes. A real repository, so every change is visible, reversible and attributable. Access to the deployment target, so "it works on my machine" is not the end of the conversation. The logs and monitoring, so a claim about production can be checked against production. Guardrails, backups and a rollback path, so a mistake costs minutes instead of a client. And a human process around all of it, because an agent with root access and no supervision is not a strategy.
An agent with that environment can finish work. An agent without it can only make suggestions about work. That gap is the difference between a colleague and a chat window.
The model still matters, just less than you think
I am not going to pretend the model is irrelevant. It is not. A weak model inside a perfect environment still writes weak code, and you will pay the difference in review time.
But the ceiling most people assume is far lower than it actually is, and the floor is much higher than they expect. A competent model with a real environment will beat an excellent model with a chat box and a guess, consistently, on any task that has to touch a system. That is why I do not sell the most expensive model on the market. I sell the setup around it: the server, the deployment, the version control, the guardrails, and the judgement of people who have run production systems for a long time.
What we are actually selling
Our agents are pre-trained by senior web developers. That sentence is doing a lot of work, so let me be concrete.
It means the agent inherits how we work. How a repository should be structured. What a safe deployment looks like. What a code review catches. Where a TYPO3 installation breaks under load. Which server settings are a liability. What to check before telling a client something is finished. Those are not model features. They are twenty years of web development and server management, written into the agent's skills, its tools and its rules.
That is also why we can hand a client an application that is versioned, deployed and running, instead of a folder of files and a good feeling.
Other providers sell you access to a model. We sell you the machine it runs on, the skills it starts with, and the people who built both.
If you want to see what that looks like for your business, book a free consultation. Bring the messy part. That is the part we are good at.
Ready?
Let's talk about your AI Agents
Speak with an experienced expert who knows what they are talking about.